Sarvam AI · Sarvam 105B ConversationsMay be chunk-batched.
Compare India inference performance
Measure the model. Not the claim.
We tested the same Indian models on JarvisLabs, Sarvam AI, and E2E Networks Blaze. These are single-stream probes with recorded prompts and sample sizes, not vendor speed claims. TTFT, end-to-end TPS, fixed-workload cost, and reliability stay separate.
E2E Networks Blaze · GLM 5.3 Flash · TPS per ₹
Sarvam AI · Gemma 4 31B
228/252 tool calls · 99.2% structured
Provider summary
Who is fast, who is cheap, who is reliable.
Each provider is judged on the models it actually serves. E2E does not offer GLM 5.3, so that model is not used for the three-provider comparison.
| Provider | Models | Fastest model | TPS | Best value | TPS per ₹ | First answer | Reliability |
|---|---|---|---|---|---|---|---|
| JarvisLabs | 8 | Nemotron 3.5 Super VL 120B | 365.5 | DeepSeek V4.1 Flash | 18.1 | DeepSeek V4.1 Flash Cyber · 323 ms | 96/96 tools · 96/96 structured |
| Sarvam AI | 6 | Sarvam 105B Conversations | 654.6 | GLM 5.3 Flash | 7.9 | Gemma 4 31B · 114 ms | 72/72 tools · 72/72 structured |
| E2E Networks Blaze | 7 | GLM 5.3 Flash | 459 | GLM 5.3 Flash | 34.5 | Gemma 4 26B A4B · 115 ms | 60/84 tools · 82/84 structured |
JarvisLabs 8 models
- Fastest
- Nemotron 3.5 Super VL 120B
- TPS
- 365.5
- Best value
- DeepSeek V4.1 Flash
- TPS per ₹
- 18.1
- First answer
- DeepSeek V4.1 Flash Cyber · 323 ms
- Reliability
- 96/96 tools · 96/96 structured
Sarvam AI 6 models
- Fastest
- Sarvam 105B Conversations
- TPS
- 654.6
- Best value
- GLM 5.3 Flash
- TPS per ₹
- 7.9
- First answer
- Gemma 4 31B · 114 ms
- Reliability
- 72/72 tools · 72/72 structured
E2E Networks Blaze 7 models
- Fastest
- GLM 5.3 Flash
- TPS
- 459
- Best value
- GLM 5.3 Flash
- TPS per ₹
- 34.5
- First answer
- Gemma 4 26B A4B · 115 ms
- Reliability
- 60/84 tools · 82/84 structured
Throughput and latency
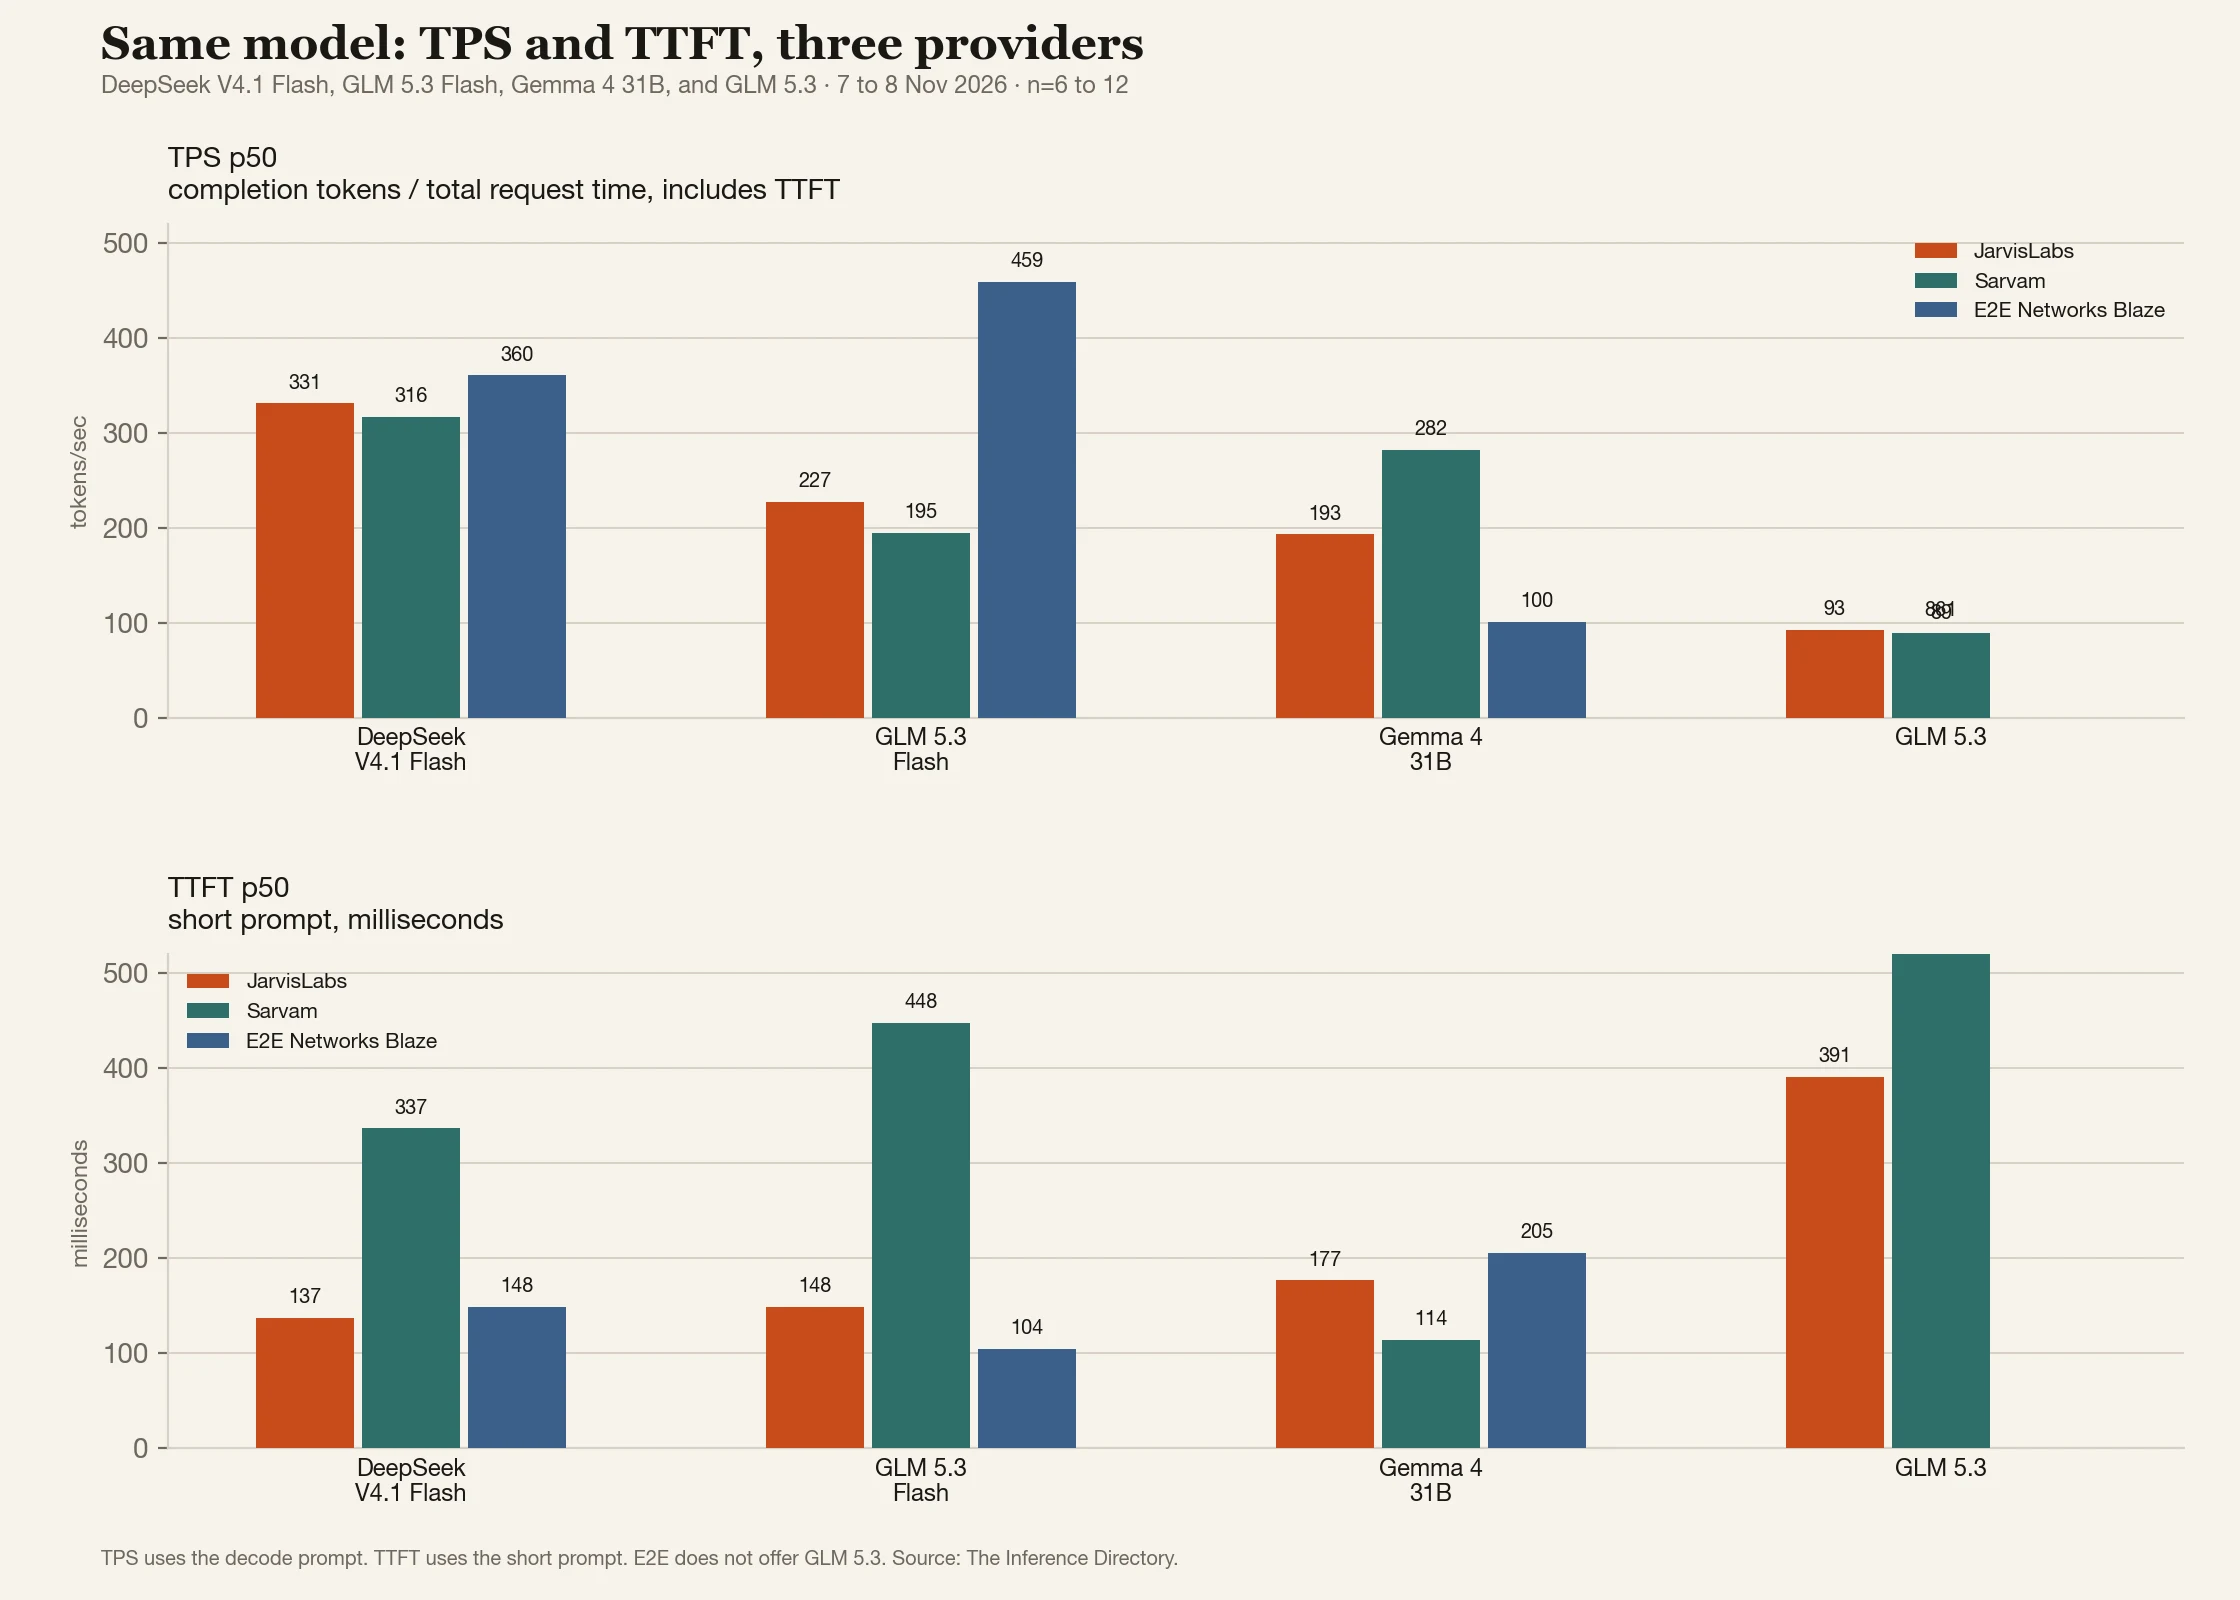
The same model behaves differently on each provider.
TPS p50 is end-to-end completion tokens divided by total request time. TTFT p50 is the first token, which can include reasoning before any answer text.
Speed and cost
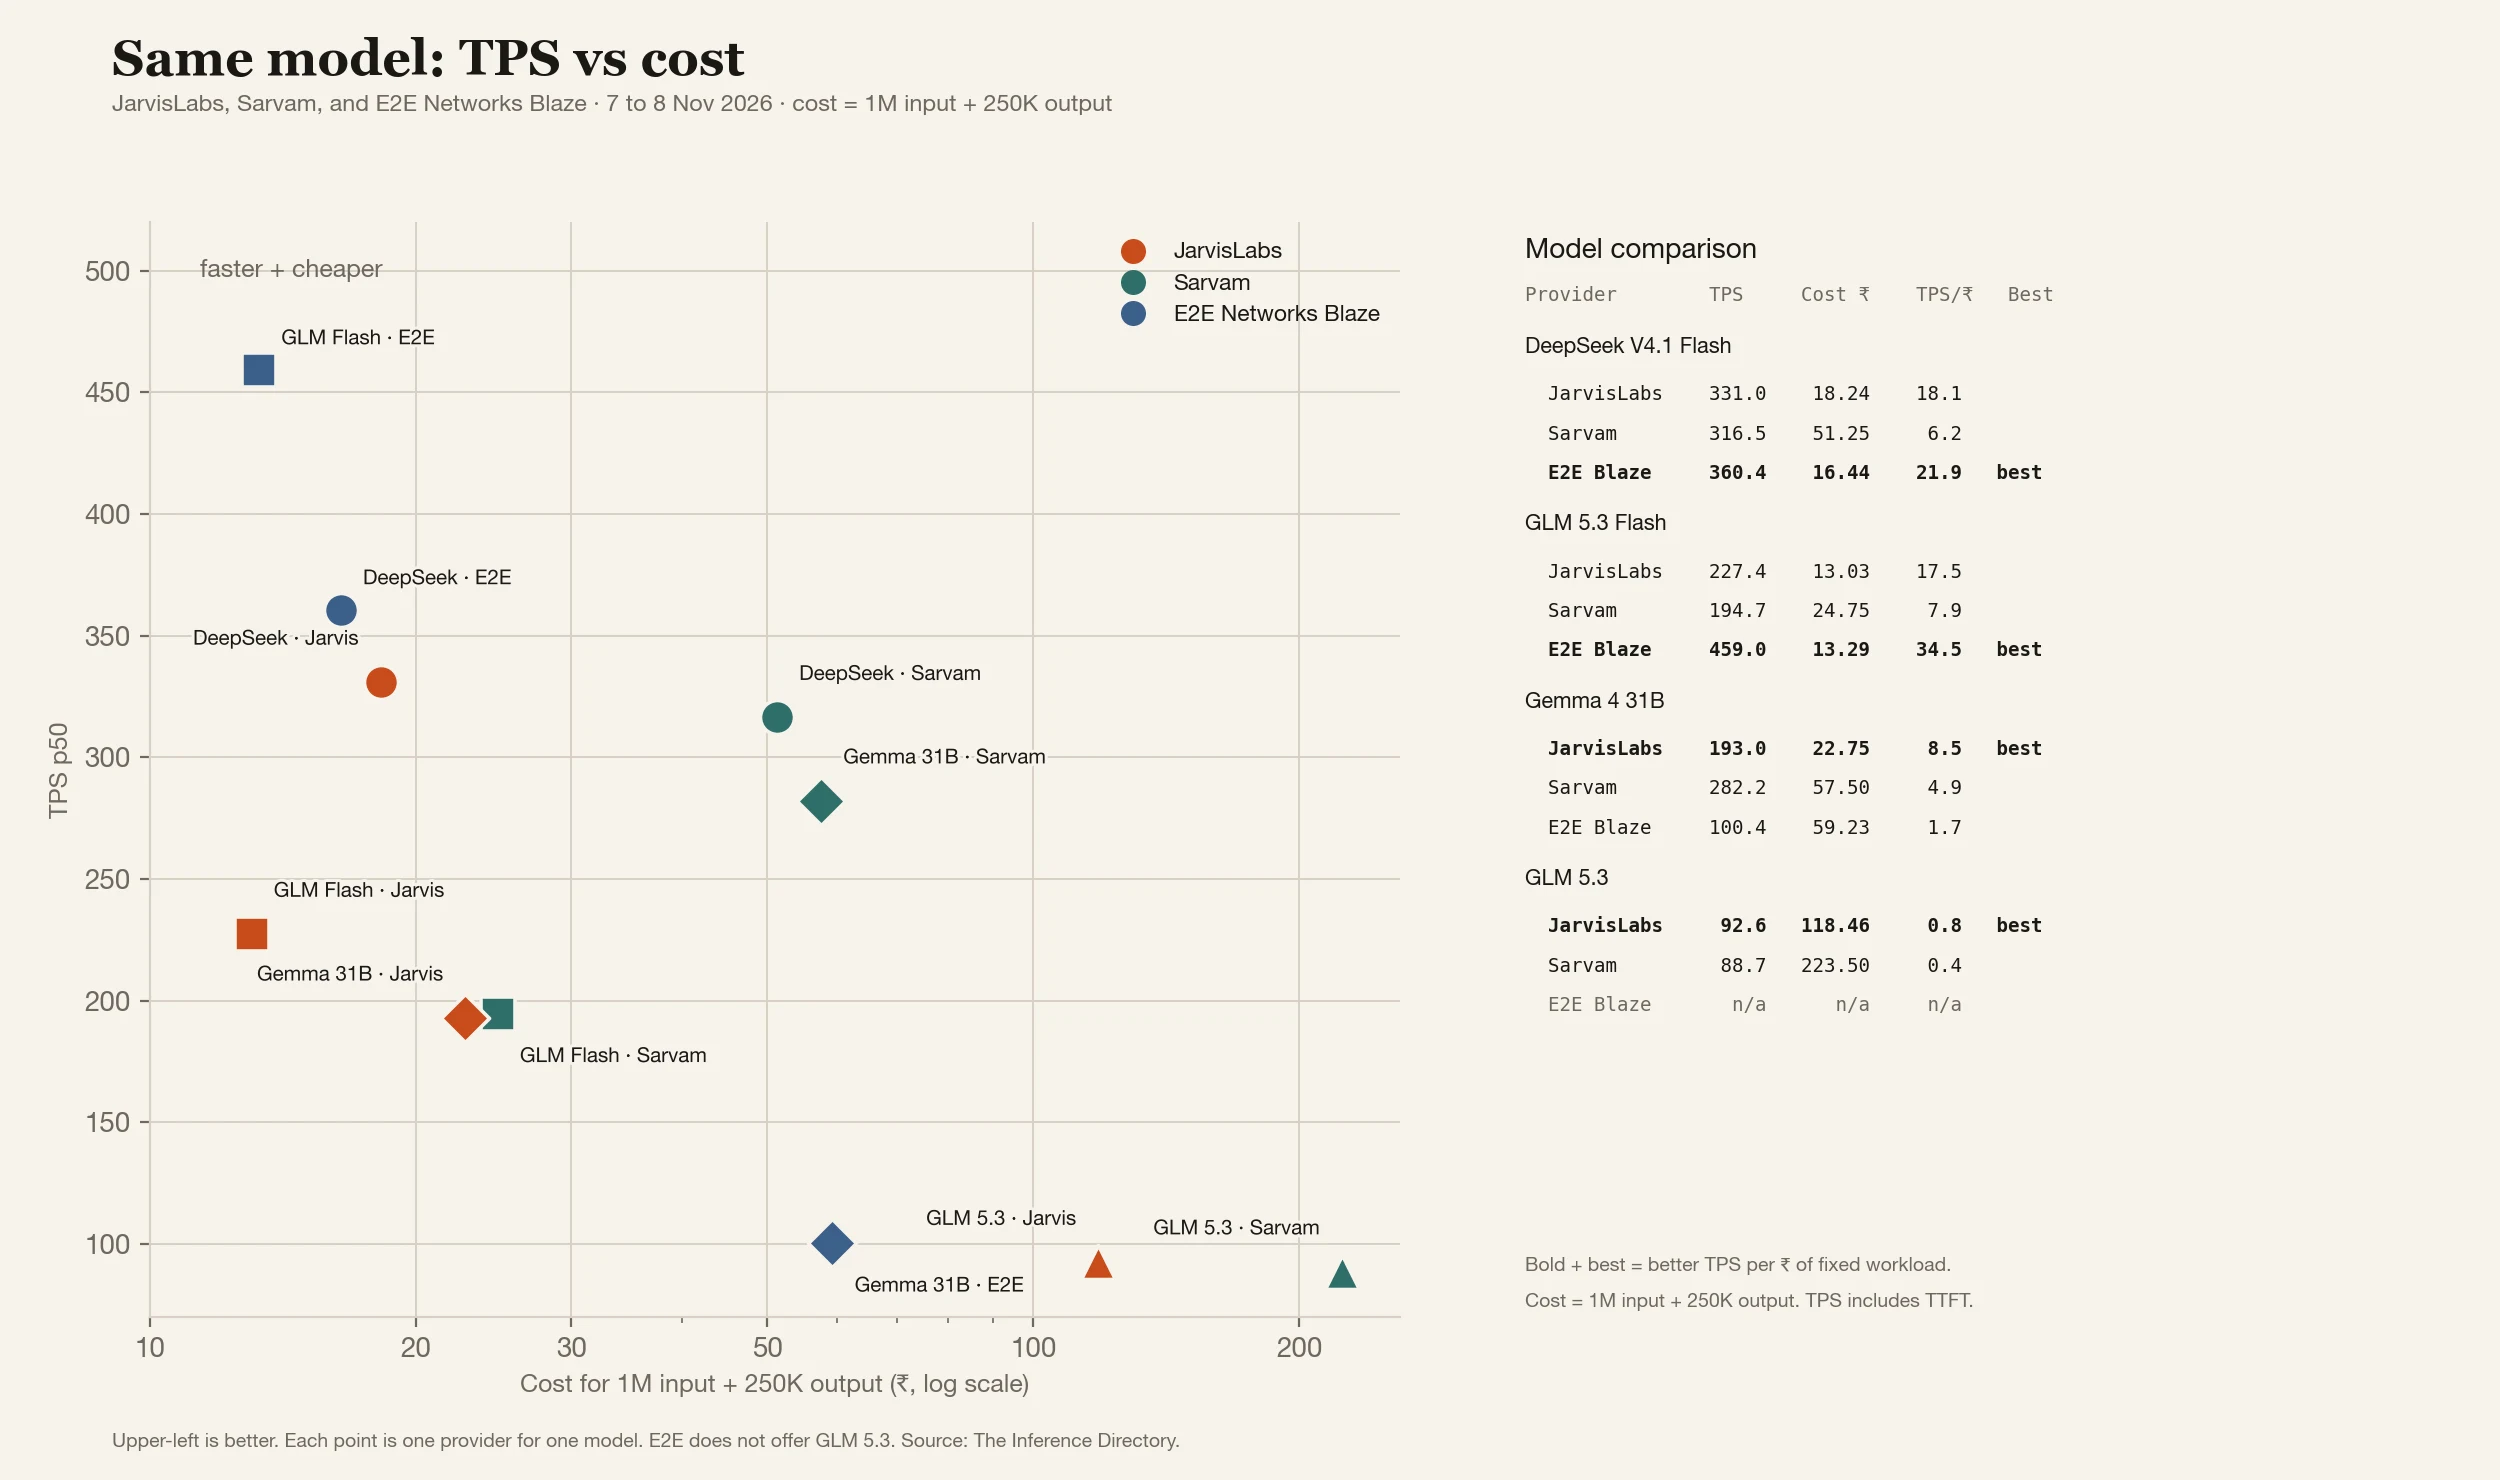
Faster is not always better value.
Cost is 1M input tokens plus 250K output tokens at list rates. The side table keeps TPS, cost, and TPS per ₹ visible together.
Method
What the numbers mean.
These are repeatable probes, not a load test. The same prompt set and sample rules were used for each provider.
TTFT and first answer
TTFT is the first non-empty streamed delta, including reasoning. First answer is the first content delta after reasoning. Short prompt is 287 to 313 input tokens. Long prompt is about 12K input tokens.
End-to-end TPS
TPS is completion tokens divided by total request time, including TTFT. Decode TPS excludes TTFT and is shown only as a secondary number. The decode prompt asks for the integers 1 to 100.
Fixed workload cost
Cost is 1M input tokens plus 250K output tokens at list rates, excluding GST and cache hits. TPS per ₹ divides end-to-end TPS by that fixed-workload cost.
Tools and structured output
Six tool cases and six JSON-schema cases, two samples each. Tool calls are checked for valid JSON, known tool names, and expected argument values. Structured output is checked against the schema.
n=6 to 12 per cell. Single stream, 1.5 seconds between requests, default reasoning. No concurrency and no load testing. Sarvam 105B Conversations may be chunk-batched and is excluded from best-value picks. E2E Qwen3.5-9B has about 8K effective context on this route.
Read next
Pick the model, then pick the provider.
Use the provider profiles for pricing, compliance, and model access. Use the India inference guide for the pricing and comparison method.